Storing Market Time Series Without Drowning in Data
Most of what a naive collector records says nothing happened. Sampling, change-only writes and sensible retention keep a useful history small.
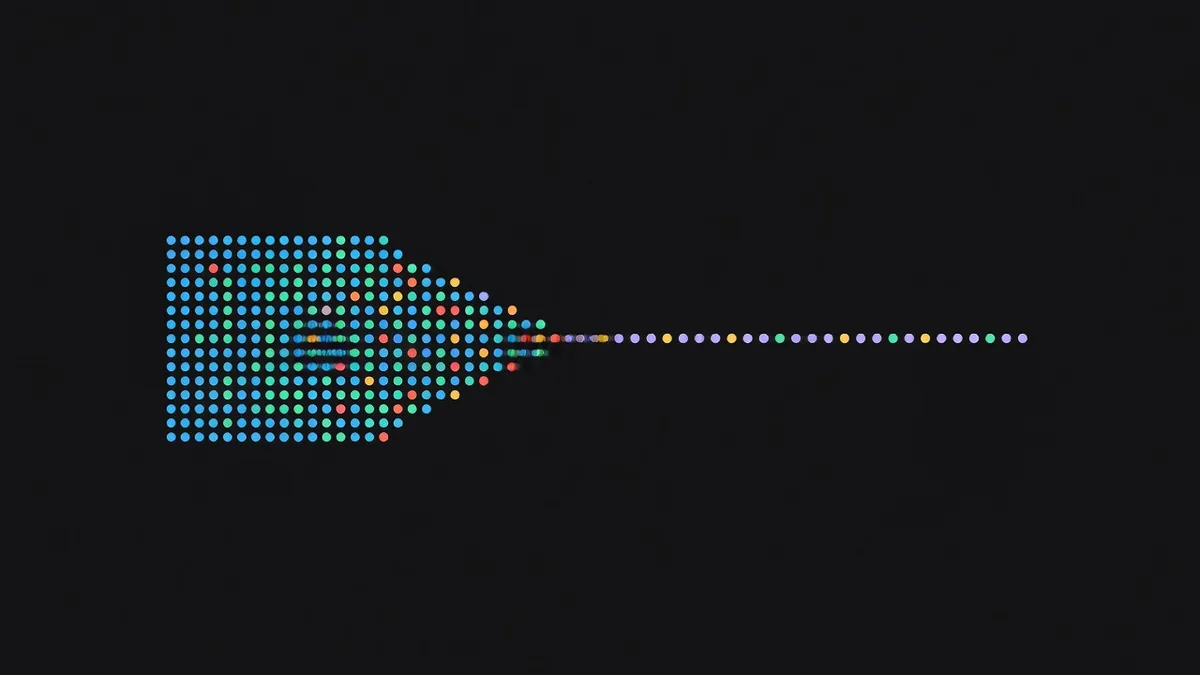
Poll a thousand markets every thirty seconds and you will write about three million rows a day, of which the overwhelming majority record that nothing changed. Storage is cheap; queries over pointless data are not.
Write on change
The single biggest saving. If bid, offer and sizes are identical to the last recorded row, do not write a new one. Write a row when something changes, plus a heartbeat row at a low frequency so you can distinguish "unchanged" from "collector was down".
On a typical prediction market universe this cuts volume by an order of magnitude or more, because most markets genuinely do not move.
Sample by interest, not uniformly
A watchlist of fifty liquid markets deserves frequent sampling. The other several thousand deserve hourly at most.
Making this dynamic — promote a market to frequent sampling when it becomes active, demote it when it goes quiet — gets you most of the resolution where it matters at a fraction of the cost. Rate limits and polling.
Tier by age
Recent: everything, at full resolution.
Older: periodic snapshots — hourly or daily bars with open, high, low, close on the mid, plus volume.
Archive: daily summaries, indefinitely.
Nobody needs thirty-second resolution on a market that settled eight months ago, except around the event itself. Keeping full resolution in a window around each settlement and summarising the rest gives you almost all the analytical value at a small fraction of the size.
Keep the cheap fields, drop the expensive ones
Resolution criteria are long text and nearly static. Store one copy with a hash, and reference it, rather than repeating it on every row.
Depth beyond the top few levels is large and rarely used. Top three levels each side is usually enough for slippage work. Depth and slippage.
Schema notes that save pain later
Store prices as integers in cents. Floating point on bounded prices produces comparisons that fail for no visible reason.
Store timestamps in UTC, always. With the venue's observation time and your fetch time as separate columns. Detecting stale data.
Store the outcome separately from the price series, joined by market id.
Never overwrite. If a venue corrects a value, write a new row. The history of what you saw is more valuable than a tidy current state, and it is the only defence against lookahead bias. Backtesting honestly.
Indexing
Almost every query is "this market, this time range" or "all markets, this moment". Index on market id plus timestamp, and keep a small current-state table updated on write for the second pattern. A dashboard that scans a full history to render a page will be slow long before the data is large.
The pragmatic target
A year of useful history on a few thousand event markets, with change-only writes and tiered retention, is a small database. It fits comfortably in modest infrastructure and queries fast.
The naive version of the same thing is enormous, slow, and no more informative.
Next
Educational content only. Nothing here is financial advice, a solicitation, or an offer to trade. Prediction markets can move against you and a position can lose its entire value. Where this guide describes a difference between venues it describes a theoretical cross-market edge in observed prices, which is not a profit: fees, spreads, capital lockup, transfer time and differing settlement rules all come out of it first.
Keep reading
 Data and Automation · 3 min readHistorical Price Series and Their PeculiaritiesEvent contract history is not like equity history. Fixed bounds, a settlement point, irregular trading and a survivorship problem built into the data.
 Data and Automation · 3 min readRate Limits, Polling, and Not Being a NuisanceA polling schedule that matches where the information actually is will use a fraction of the requests and produce better data than polling everything.
 Data and Automation · 3 min readWorking With Public Prediction Market APIsWhat public endpoints give you across venues, the fields that matter, and the habits that keep a data pipeline working and welcome.
 Prices and Probability · 3 min readWhen the Outcomes Do Not Add to 100%A field of outcomes should sum to one dollar. When it sums to more, you are seeing the spread. When it sums to less, something is missing or stale.